 INFRA
INFRA


INFRA

For the past two years, enterprise AI investment has been dominated by one conversation: compute. Organizations raced to secure GPU allocations, negotiated infrastructure deals and stood up machine learning platforms at speed. What many discovered only after the fact is that the bottleneck they thought they were solving was not the only one in the room. Storage is now throttling the very accelerators enterprises fought to acquire.
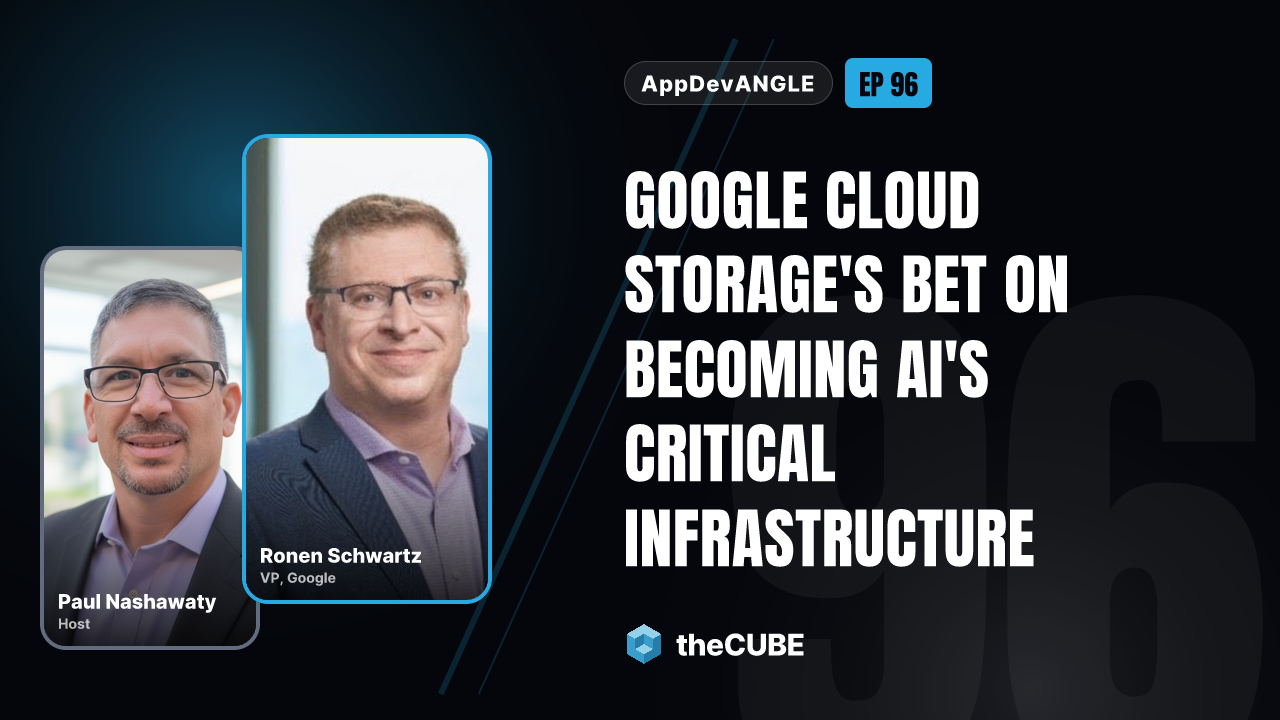
In the latest episode of the AppDevANGLE podcast, I spoke with Ronen Schwartz, vice president of products for Google Cloud Storage at Google LLC, about why storage has quietly become the defining constraint in enterprise AI infrastructure, and what a purpose-built architecture for AI workloads actually looks like. The conversation cuts to a problem that is real, measurable and still largely underacknowledged in most AI strategy discussions.
“Storage just got promoted,” Schwartz said. “Instead of being at the backend as an enabler, it is moving into the front as a critical part of accelerator execution.”
The economics of this problem are direct. Accelerators are, as Schwartz put it, an enterprise’s most expensive line item. Every second they idle waiting for data is money lost — not in some theoretical efficiency calculation, but in immediate, traceable waste. Yet when teams finally get access to their TPUs or GPUs, the data delivery path often hasn’t received the same attention as the compute layer.
“I speak to many customers, and what I’m hearing is the team spent a long time fighting to get their TPUs, their GPUs, to get their hands on accelerators. And once they got them, they’re actually not always able to get the output they needed. Very often it actually goes back to not enough thought put into the data delivery path.”
This is not a fringe scenario. Schwartz described a pattern where organizations identify the storage bottleneck only after it hits them — when GPU utilization metrics fall short of targets and training timelines stretch beyond projections. By then, the cost of underinvesting in storage architecture is already embedded in the project.
One of the clearest insights from the conversation is that AI is not a single workload, and treating it as one creates compounding gaps in storage architecture. Schwartz described training, inference and agentic workloads as having fundamentally different “heartbeats” with distinct data movement patterns that each require targeted design.
Training demands massive sequential reads, but the equally critical pressure point is checkpoint management. Every 15 minutes or so, a training cluster must pause and write a multi-terabyte checkpoint to protect work done against potential failure. “Slow storage in that place freezes the entire GPU cluster,” Schwartz said. Google’s Rapid object storage technology, he noted, can write checkpoints more than three times faster and restore them more than five times faster than standard object storage, and this distinction matters significantly at scale. He pointed to Torin, an autonomous vehicle company, as an example: millions of sensor data points flowing into storage to train vehicle models, where checkpoint performance is not an edge case but a core operational requirement.
Inference introduces a different constraint entirely, that of real-time, latency-sensitive interaction where response time directly affects user experience and token economics. Agentic workloads layer on a third set of demands: shared workspaces, state persistence across agents, low-latency retrieval and the need to support both short-lived and long-running agent processes that may hibernate and reactivate on demand.
“AI is not one workload. Really, the movement of data looks completely different. It’s like different heartbeats depending on where you are in the lifecycle.”
Google’s differentiation argument centers on infrastructure credibility built over years of running hyperscale AI workloads internally before offering the same capabilities externally. Schwartz cited specific performance figures: 15 terabytes per second on Rapid object storage and 10 terabytes per second on Google Cloud managed clusters, which he described as verified industry-leading numbers.
The technical foundation includes zonal colocation, or placing data physically close to GPU and TPU clusters to minimize the time a byte travels to the accelerator. Schwartz described this as a first-to-market capability that required rethinking assumptions baked into traditional storage design, where multi-zone or multi-region distribution was the default goal. For AI workloads, proximity to the accelerator takes priority. Google’s Rapid Bucket technology reduces processing steps in the storage path, enabling a single bucket to deliver more than 15 terabytes per second throughput with support for 20 million queries per second at sub-millisecond latency.
“It is because it is built on the Google infrastructure, which has been used internally longer than anyone else to support accelerators and their performance. But it is also because Google is working with nine out of the ten world-leading AI frontier model companies.” A storage architecture that can demonstrably improve GPU utilization can provide faster iteration through less idle compute and lower effective cost per training run.
The agentic dimension of the conversation revealed an underappreciated wrinkle in enterprise AI readiness. Agents require more than web browsing and database queries; they need access to unstructured data at scale, including images, video, documents and PDFs that represent the bulk of most organizations’ real data assets. Without a way to make that content semantically accessible, agents operate with a restricted and often unrepresentative view of enterprise knowledge.
Google’s response is what Schwartz called a Smart Storage Initiative, anchored by a recently launched Object Enrichment capability. When a file or image lands in a storage bucket, Google AI models automatically extract content and attach structured metadata to the object — in seconds, and at scale. The result is that what was previously unstructured becomes queryable by agents without manual intervention or downstream processing pipelines.
“An agent can now interact with what used to be called unstructured data because there is actually a very good understanding of the content.” The storage layer is also integrated into Google’s broader agentic data cloud and borderless lakehouse architecture, allowing agents to reach data stored outside Google’s environment as well.
For agent infrastructure at scale, Schwartz described dedicated Filestore agent volumes integrated directly into Google Kubernetes Engine and the agent sandbox environment, designed specifically to handle the cost, response speed, and data-sharing requirements of running thousands or millions of agents simultaneously.
The broader market shift here is architectural, not incremental. Enterprise AI infrastructure has been built in layers (compute first, then frameworks, then data) and storage was often treated as a procurement checkbox rather than a performance variable. That sequencing is proving costly. As GPU utilization targets become measurable KPIs and AI operations budgets face tighter scrutiny, the storage layer is being reassessed in a way it hasn’t been in years.
What Google’s position illustrates is that hyperscale operational experience at the storage layer translates directly into enterprise advantage — not as a marketing claim, but as a measurable difference in checkpoint speed, throughput, latency and agent responsiveness. The companies that have been running frontier model training and inference at scale have been forced to solve these problems; enterprise teams are now encountering them for the first time.
For platform engineers, ML infrastructure teams and enterprise architects, the implication is specific: Storage architecture decisions made during initial AI platform buildout will constrain or enable performance for every workload that follows. Revisiting those decisions after the bottleneck appears is significantly more expensive than addressing them in the design phase.
The market is heading toward a point where AI infrastructure conversations routinely include storage as a primary tier, not an afterthought. Organizations that recognize that shift early will extract measurably more value from the accelerator investments they have already made.
To hear the full conversation with Ronen Schwartz, check out the latest episode of the AppDevANGLE podcast. To learn more about how Google Cloud Storage can support the evolving demands of enterprise AI, explore Google’s storage solutions or connect with the Google Cloud team to discuss the right approach for your organization’s workloads.
Here’s theCUBE Research’s complete interview with Google’s Ronen Schwartz:
Support our mission to keep content open and free by engaging with theCUBE community. Join theCUBE’s Alumni Trust Network, where technology leaders connect, share intelligence and create opportunities.
Founded by tech visionaries John Furrier and Dave Vellante, SiliconANGLE Media has built a dynamic ecosystem of industry-leading digital media brands that reach 15+ million elite tech professionals. Our new proprietary theCUBE AI Video Cloud is breaking ground in audience interaction, leveraging theCUBEai.com neural network to help technology companies make data-driven decisions and stay at the forefront of industry conversations.